Update 4 September 2026: OpenAI has released GPT-6 Astra. What reaches your ChatGPT plan and what it costs is covered in GPT-6 Astra: availability and pricing.
Anthropic released Claude Fable 5.1 on September 1, 2026. In the published tests, the model solves considerably more tasks than its predecessor Fable 5, than the cheaper Opus 5, and than OpenAI's GPT-5.6 Sol – especially in scientific research and business-process automation. Per-token prices stay the same, but Fable 5.1 uses fewer of them: typical workloads become about 25 percent cheaper, according to Anthropic. There is still a catch, and it is not in the announcement: from September 14, subscribers effectively get about 17 percent less weekly quota in Claude Code than they have today – even though Anthropic presents the change as "25 percent more usage". The math behind that is further down.
Contents
- What the percentages in benchmarks mean
- The benchmark results at a glance
- Where Fable 5.1 is truly far ahead – and where it is not
- What Fable 5.1 costs – and why "same price" is still cheaper
- Which model for which task? Three recommendations
- The quota fine print: +25% announced, −17% in practice
What the percentages in benchmarks mean
A benchmark is a fixed set of exam tasks that every model gets under the same conditions – like a class test that several students sit. The percentage tells you how many tasks the model solved. "Terminal-Bench 4.0: 55.8%" therefore means: Fable 5.1 completed 55.8 percent of these test tasks correctly.
Three things help put the numbers in context:
- No model reaches 100 percent. The tasks are deliberately so hard that even the best systems fail. 55 percent can therefore be a top score – what matters is the gap to the other models, not the absolute number.
- Every benchmark tests something different. A model can be strong in the coding test and weak in the science test, just as a student can excel at math and struggle with English.
- One number in the table is not a percentage: GDPval-AA is an Elo rating like in chess. Raters compare two answers and pick a winner, which produces a ranking number. 1,853 versus 1,824 means: Fable 5.1 wins such duels slightly more often than Opus 5.
And one caveat that applies to every model announcement: the numbers come from the vendor itself. Anthropic chooses which tests appear in the announcement – plausibly the ones where its own model looks good. Independent re-tests usually appear days to weeks later.
The benchmark results at a glance
All numbers come from the Anthropic announcement of September 1, 2026. The best value is in bold.
| Benchmark (what it tests) | Fable 5.1 | Fable 5 | Opus 5 | GPT-5.6 Sol |
|---|---|---|---|---|
| Terminal-Bench-Science 0.1 (scientific research tasks) | 52.6% | 24.7% | 29.0% | 22.4% |
| Terminal-Bench 4.0 (working independently on the command line) | 55.8% | 42.0% | 52.3% | 37.3% |
| AutomationBench (automating business processes) | 31.4% | 17.1% | 26.9% | 19.6% |
| GDPval-AA v2 (office and knowledge work, Elo rating) | 1,853 | 1,723 | 1,824 | 1,711 |
| OSWorld 2.0 strict (operating a computer like a human: windows, clicks) | 41.7% | 36.1% | 39.6% | — |
| Humanity's Last Exam without tools (hard expert knowledge across all fields) | 60.9% | 57.8% | 56.6% | — |
| CursorBench 3.2.0 (programming in a code editor) | 73.4% | 70.5% | 70.0% | 67.2% |
Where Fable 5.1 is truly far ahead – and where it is not
The table shows two very different pictures, depending on where you look.
There are big jumps in two task types. In scientific research tasks (Terminal-Bench-Science), Fable 5.1 solves more than twice as many tasks as its own predecessor at 52.6 percent – leaving Opus 5 (29.0%) and GPT-5.6 Sol (22.4%) far behind. Similar in business-process automation (AutomationBench): 31.4 percent versus 17.1 percent for the predecessor. These are exactly the long, multi-step tasks where the model has to plan on its own, use tools, and check intermediate results. Anthropic gives a research example: in designing protein binders, Fable 5.1 achieved a hit rate of nearly 50 percent, where 10 to 15 percent is considered typical.
The gap stays small in everyday coding and factual knowledge. In the editor test CursorBench, only 2.9 percentage points separate Fable 5.1 from its predecessor; in the knowledge test Humanity's Last Exam, 3.1. If you use the model for normal code and text tasks, you will barely notice the difference in daily work.
In short: Fable 5.1 is above all a model for long, independent chains of work – research, analysis, processes that take many steps. For the quick one-off task in between, the lead is small.
What Fable 5.1 costs – and why "same price" is still cheaper
The list prices via the developer interface (API) are unchanged – the savings come from elsewhere:
| Item (per 1 million tokens) | Fable 5.1 | Fable 5 | Opus 5 | GPT-5.6 Sol* |
|---|---|---|---|---|
| Input | $10 | $10 | $5 | $4 |
| Output | $50 | $50 | $25 | $20 |
| Cached input (cache reads) | $0.25 | $1.00 | — | — |
\* Promotional price until at least November 21, 2026; list price $5/$30.
Tokens are the billing unit of AI providers – roughly a fragment of a word. And this is the real price lever: Fable 5.1 uses fewer tokens for the same work. Anthropic puts the savings at about 25 percent for typical workloads and up to 45 percent for long, independent chains of work. The financial data provider Bloomberg reports from its own tests that the model was about twice as fast as Opus 5 and used half as many tokens. On top of that comes the cache price: if you send the same documents along repeatedly – the normal case in longer working sessions – you now pay only a quarter of the previous price for those repetitions.
Which model for which task? Three recommendations
Price and test results together yield three simple rules of thumb. They reflect the state of September 2026 and are based on the vendor numbers above:
- Everyday tasks – texts, emails, translations, normal coding tasks: the mid-range is enough here. Claude Sonnet 5 ($2/$10 per million tokens) or GPT-5.6 Sol ($4/$20) handle this work at a fraction of the Fable cost; for short single tasks, the quality difference is barely noticeable. If you work on a Claude subscription, this also protects your weekly quota, because Fable weighs doubly heavy there (see below).
- Hard single tasks – a tricky bug, contract analysis, a complex evaluation: Claude Opus 5 ($5/$25) is the price-performance sweet spot. In most tests it trails Fable 5.1 by only a few points, but costs half as much.
- Long, independent chains of work – research across many sources, multi-step automation, scientific analysis: this is where Fable 5.1 plays its lead, twice over: it solves considerably more of these tasks (52.6% versus 29.0% for Opus 5 in the science test) and needs fewer tokens to do it. For this kind of work, the more expensive model can end up the cheaper one – measured by cost per completed task, not per request.
The quota fine print: +25% announced, −17% in practice
Alongside the model announcement, Anthropic communicated a change to usage limits: from September 14, 2026, the standard weekly limits in the programming tool Claude Code rise permanently by 25 percent – for the Pro, Max, Team, and Enterprise seat plans.
What the announcement leaves out: since May, a temporary 50 percent increase has been in place, extended several times, and it expires on September 13. The math therefore looks like this:
| Weekly quota (base = 100) | |
|---|---|
| Original limit | 100 |
| Today (temporary +50%) | 150 |
| From September 14 (permanent +25% on the old base) | 125 |
Compared with the original limit, that is indeed 25 percent more. Compared with what users have been accustomed to for months, it is about 17 percent less (125 instead of 150). Both statements are true – the announcement just tells the first and omits the second. Trade media such as BleepingComputer have retraced the calculation.
For Fable models on subscriptions, the rule remains unchanged: on Max and premium seats you may spend at most half of your weekly limit on Fable; after that you buy extra credits or switch to a smaller model. On the Pro plan, Fable runs on paid extra credits from the start. The fact that Fable 5.1 is more economical with tokens softens this in practice – it changes nothing about the limit itself.
If you are working out which AI tools pay off for your business: how the model families from Anthropic and OpenAI have evolved is covered in our articles on GPT-5.6 Sol, Terra and Luna and the eventful history of Claude Fable 5. This guide appears on office1.cloud, where freelancers also handle invoices and bookkeeping.
Handle invoices more easily
Easy Invoice combines quotes, invoices and customer management in the cloud.
Try Easy InvoiceRead next
 World News
Club Management Software for Football Clubs: Website, App and Fixtures for €39.99 a Month
Fixtures arrive on their own, results too, parents cancel from their phones and the summer tournament has an online entry form: what the club software ligantor takes off a football club week after week – and what it costs.
 World News
Making Money on Twitch in 2026: Monetization Is Now Open to Everyone – and What That Means for Your Taxes
Twitch is making monetization open to everyone in 2026 and lowering the Affiliate hurdles. What that means for you – and when a hobby turns into taxable side income.
 World News
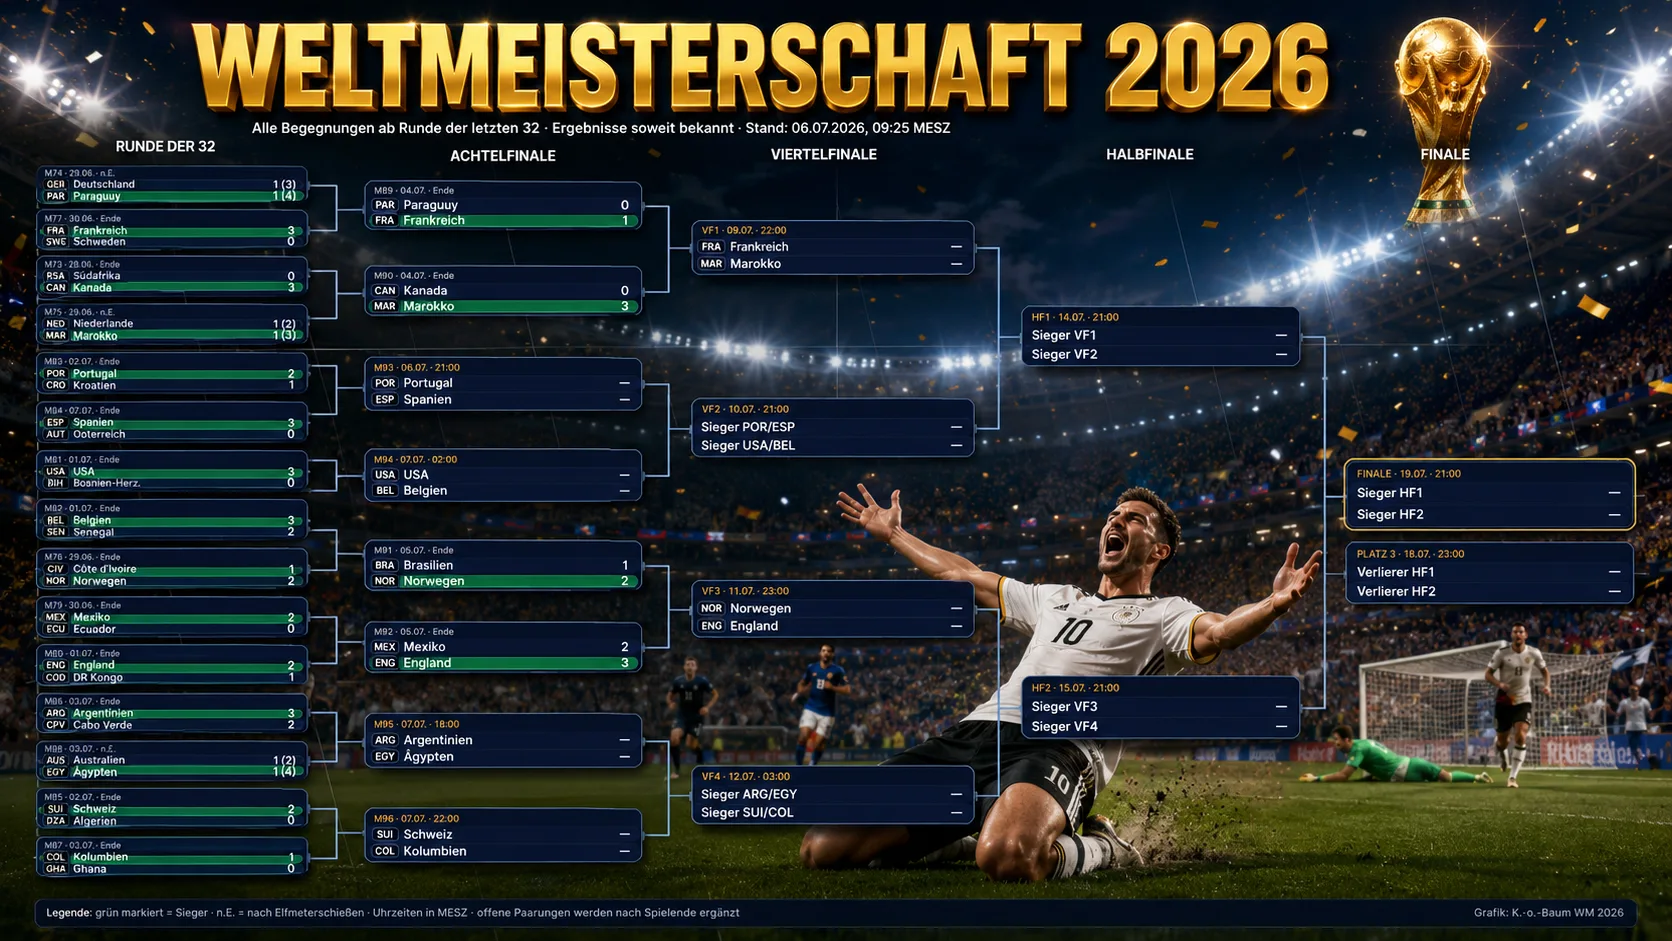
World Cup 2026: The Knockout Stage Is On – Round of 16 With Heavyweights
The 2026 World Cup has left the group stage behind and entered the knockout phase. Plenty is new: 48 teams, an extra round of 32, unfamiliar kick-off times from North America. An overview of the format, the state of play and the heavyweight round-of-16 ties.